Sean left a comment referring to a post by James Clark on TEDI, a new kind of schema language for XML. It's a very interesting post. I like how it elevates the issue to one of defining a common data meta-model, with mappings to the plethora of formats which are all basically trying to do the same thing (XML, JSON, YAML, etc).
However, I think I noticed something missing in the TEDI concept. This is the ability to define complex types which are composed of combinations of basic data structures. XML Schema of course does have this feature, and it's responsible for a significant part of the perceived complexity. But a schema language which lacks this ability is limited in its expressiveness. A sterling example is GML Geometry. Geometric types are complex enough that they have to be defined in terms of simpler XML data structures. One of the goals of GML is to provide a meta-schema which defines the concept and structure of expressing geometric datatypes in XML. To accomplish this, the concept of a Geometry datatype needs to be expressible at the schema level.
Of course, for any given application domain you can dodge this issue by simply relying on convention. A datatype with more than trivial semantics is going to have a custom implementation in any given system, so a custom mapping from XML will be needed in any case. But that's not really the point - surely at this stage of computer science we can do better than arbitrary convention?
I haven't yet seen an explanation of whether RELAX-NG provides this level of expressiveness. I don't see it in JSON or YAML. But it seems like this capability is essential for any schema language which is going to take us beyond simply collections of a small set of datatypes.
Thursday, 30 August 2007

Wednesday, 29 August 2007
RELAX NG good, XML Schema bad?
Here's a nice post on why RELAX NG is better than XML Schema. Since data modelling and language expressiveness are a major interest, I'm finding it fascinating to watch the evolutionary battles in the world of "meta-XML".
One key point made is that RNG is much easier to grasp than XML Schema. Witness this short tutorial which tells you most of what you need to know.
Something I haven't fully understood yet is why RNG fans consider PSVI to be a bad idea. As far as I see, any tool which is a general purpose parser for typed XML is going to have to define a metamodel describing the allowable range of documents. Doesn't it make sense to have a standard model for this?
Another thing I don't see is whether and how RNG supports the constrained extensibility of schemas (i.e. subclassing). This is responsible for a fair bit of the complexity in XML Schema, but is essential in some uses (such as GML, which is really a schema framework for defining other concrete schemas).
Probably the most appealing aspect of RNG is its compact syntax. It's much more readable than XML. (XML is a terrible syntax for expressing a hierarchical language!). Of course, this means the end of the "one parser to scan them all" dream - but perhaps that's a good thing. Come back, YACC, we really didn't mean it and we still love you!
This post gives a rebuttal to the RNG-over-XSD argument. He seems to think that RNG lacks subclassing as well, so maybe that answers one of my questions above.
One key point made is that RNG is much easier to grasp than XML Schema. Witness this short tutorial which tells you most of what you need to know.
Something I haven't fully understood yet is why RNG fans consider PSVI to be a bad idea. As far as I see, any tool which is a general purpose parser for typed XML is going to have to define a metamodel describing the allowable range of documents. Doesn't it make sense to have a standard model for this?
Another thing I don't see is whether and how RNG supports the constrained extensibility of schemas (i.e. subclassing). This is responsible for a fair bit of the complexity in XML Schema, but is essential in some uses (such as GML, which is really a schema framework for defining other concrete schemas).
Probably the most appealing aspect of RNG is its compact syntax. It's much more readable than XML. (
This post gives a rebuttal to the RNG-over-XSD argument. He seems to think that RNG lacks subclassing as well, so maybe that answers one of my questions above.
Tuesday, 21 August 2007
Streaming Delaunay Triangulation for Huge Datasets
Isenburg, Liu, Shewchuk and Snoeyink have an interesting paper on contructing Delaunay triangulations over huge datasets using a streaming technique.
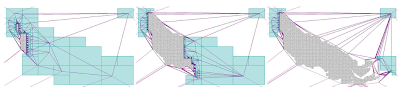
I'm quite interested in this, because here at Refractions I've just finished working on a project which involved computing a TIN for the province of B.C. using 500 million masspoints. After briefly flirting with the idea of computing a single seamless TIN, I ended up computing it in a piecewise fashion. This probably turned out to be a better approach for other reasons (such as the fact that we could easily parallelize the process). However, it would be very cool to be able to compute a seamless TIN for the entire province. And the approach in this paper sounds very effective - they quote a billion triangle in 48 minutes on a laptop!
It's also exciting to see the emergence of a whole new class of algorithms focussed on dealing with VLSD's (very large spatial datasets). As the same authors point out in another paper, paradoxically, advances in computing technology can make geospatial processing more difficult
because the rate of growth of dataset size far outstrips memory capacity.
Incidentally, these guys are a bit of a dream team for computational geometry algorithms. Shewchuck is the developer of Triangle, one of the best known programs for computing constrained 2D Delaunay triangulations (which is also AFAIK one of the few available systems to seriously address robustness issues - JTS of course being another one!) Snoeyink has done research in all kinds of different areas of CG, including interesting work in computing watershed boundaries on TINs using B.C. data.
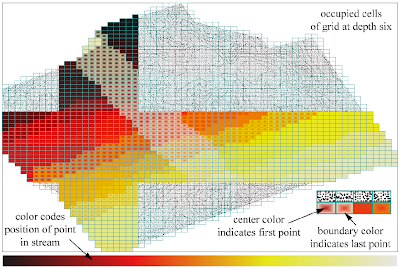
The paper also has a nice way of showing the spatial distribution of two related variables, using fill gradients:

I'm quite interested in this, because here at Refractions I've just finished working on a project which involved computing a TIN for the province of B.C. using 500 million masspoints. After briefly flirting with the idea of computing a single seamless TIN, I ended up computing it in a piecewise fashion. This probably turned out to be a better approach for other reasons (such as the fact that we could easily parallelize the process). However, it would be very cool to be able to compute a seamless TIN for the entire province. And the approach in this paper sounds very effective - they quote a billion triangle in 48 minutes on a laptop!
It's also exciting to see the emergence of a whole new class of algorithms focussed on dealing with VLSD's (very large spatial datasets). As the same authors point out in another paper, paradoxically, advances in computing technology can make geospatial processing more difficult
because the rate of growth of dataset size far outstrips memory capacity.
Incidentally, these guys are a bit of a dream team for computational geometry algorithms. Shewchuck is the developer of Triangle, one of the best known programs for computing constrained 2D Delaunay triangulations (which is also AFAIK one of the few available systems to seriously address robustness issues - JTS of course being another one!) Snoeyink has done research in all kinds of different areas of CG, including interesting work in computing watershed boundaries on TINs using B.C. data.
The paper also has a nice way of showing the spatial distribution of two related variables, using fill gradients:

Slow Forward - or back?
Here's an interesting take on the technological revolution by Gwynne Dyer (contrarian as always!). His point is that while life was dramatically transformed by numerous new technologies introduced between the 18th century and the 1950s, since then there's only really been one transformative technology, the computer (I guess he's discounting space travel since it's not generally available, or maybe because it's irrelevant?).
He has a good point, but I wonder whether he's ignoring quantitative effects of change. Sure, planes were around in the early 20th century, but they weren't allowing huge numbers of people to wash around the world in the way they do now. 9/11 would have been impossible in the 1920's, for instance. And maybe the steady improvments in speed of communication really will result in the so-called "inflection point".
But... in the end, he does mention what may turn out to be the most important quantitative effect of technological developments on humanity. His final point talks about the coming "... drastic changes in the climate that affect everything ...".
Tuesday, 14 August 2007
Engines of Logic
It seems only right that I put in a plug for the book Engines of Logic by the other, more famous Martin Davis. And here's an interesting article which reviews the book in particular reference to the occupational health hazards of being a mathematician. It's a good antidote to any regrets you might have about not being real smart.
Quote of the Day
If it wasn't for Alan Turing, I'd either be unemployed or working for the Nazis.
- unknown IT worker
- unknown IT worker
Monday, 13 August 2007
The Vietnam of Computer Science?
I couldn't resist the analogy of this blog article, even if the author slightly overstates the case. Good summary of the history of the war, too.
Makes me feel like if I haven't served a tour in the Delta, at least I've done time at a forward fire base...
Makes me feel like if I haven't served a tour in the Delta, at least I've done time at a forward fire base...
Friday, 10 August 2007
Complex Functions as Algorithmic Art
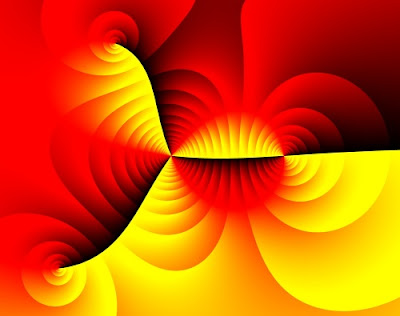
Hans Lundmark has an interesting page on visualizing complex functions. The idea is to map functions from f : C → C using position, hue, and saturation. The domain values of the function provide the (x, y) position. The function output value provides the hue and saturation; the hue is determined by the complex argument (angle), and the saturation is determined by the absolute value.
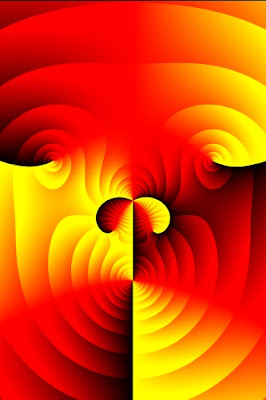
The output struck me as a nice example of algorithmic art. I whipped up my own version in Java to experiment, and to be able to produce high-resolution images for printing. Here's a couple of my images:
An example function from the paper ( f ( z ) = ( z − 2 )2 ( z + 1 − 2i ) ( z + 2 + 2i ) / z3 )
"Wild Walrus"
The output struck me as a nice example of algorithmic art. I whipped up my own version in Java to experiment, and to be able to produce high-resolution images for printing. Here's a couple of my images:
An example function from the paper ( f ( z ) = ( z − 2 )2 ( z + 1 − 2i ) ( z + 2 + 2i ) / z3 )

"Wild Walrus"

Wednesday, 8 August 2007
PreparedGeometry - efficient batch spatial operations for JTS
A common usage pattern for JTS spatial operations (in particular, predicates such as intersects and contains, and overlay operations such as intersection and union) involves the operation being invoked between a single target geometry and a batch of test geometries. For instance, this occurs in queries in a spatial database such as PostGIS, where each geometry in the driving table interacts with a set of nearby geometries via the required operation. By taking advantage of the fact that the target geometry does not change, it is possible to significantly reduce the overall execution cost of the operation. Information such as an index on the line segments in the target geometry can be computed once and cached for reuse with all of the test geometries.
In order for this to work, the calling code must be able to indicate that the operation is being invoked in a batch setting. The standard JTS Geometry API doesn't allow differentiating this case, so the new concept of PreparedGeometry has been developed. (This name intentionally echoes the concept of prepared statement in SQL API's, which implements the same strategy.) Creating a PreparedGeometry on a target Geometry enables precomputation of various data structures, which then allows subsequent operations to be evaluated with maximum efficiency.
In addition to caching, it is also possible to optimize the evaluation of spatial predicates. Optimization takes the form of short-circuiting predicate evaluation when certain situations are detected. While not all OGC spatial predicates are amenable to optimization, fortunately the most commonly usd predicates, intersects and contains, can be optimized significantly. Examples of situations which can be optimized are:
- For intersects, any intersection between line segments indicates a true result. If there is no intersection between any line segments of the operands, and the target geometry is polygonal, then one or more fast point-in-polygon tests can be performed to compute the result value.
- Since it provides more information than intersects, the contains predicate is more complex to optimize. In the case where the target geometry is polygonal, evaluation can be short-circuited when the test geometry has no line segment intersection. In this case, containment can be tested by an appropriate set of point-in-polygon tests. It is also possible to short-circuit in some specific cases where a proper intersection is detected between two line segments. Both of these situations can be tested efficiently.
Saturday, 21 July 2007
Flex VS Silverlight - another shot in the war
Another interesting post by Kurt Cagle on The Open-Sourcing of FLEX (no, I'm not paid to shill for Kurt - even if we do live in the same town). I've been wondering how the Flash/Silverlight war was going to evolve, but I'd missed this turn of the strategy. Kurt has some interesting points:
- Open Source is a weapon to gain market share
- Does this promote the slow death of SVG? And will Mozilla team up with Adobe to promote Flex? (If so, maybe this answers the question about how the OS community will provide a story to reply to Silverlight)
- Does OS-ing Flex enhance Adobe's ability to improve the technology with feedback from OS adopters?
Friday, 20 July 2007
Where is XML going?
Kurt Cagle has an interesting post on "Where is XML going".
One of his bold predictions is that SQL databases (by which I think he means relational DBs) are going to plateau and slowly be replaced by XML-based DBs. I find that a fascinating possibility. Certainly the emergence of XQuery finally provides a decent query language for XML (and it's interesting to note that it draws from or at least parallels many SQL concepts).
One question I have is whether the XML information model is in fact more expressive than the relational model. It certainly seems so, since you can easily represent a table in XML, but the converse is not so simple. XML contains implicit information about hierarchy, which must be supplied in a relational model. It seems like there should be some sort of information content metric which could be used to determine which model is more powerful. Although, perhaps the human factors are in the end more important.
Also, to me it feels like XML suffers from too much concern with syntax (whereas relational is a pretty pure data model). There's also the cruft of elements versus attributes, processing instructions, etc. All of these complicate the XML model without bring a lot more data expressiveness. Perhaps simple use patterns will emerge and we'll all just get used to ignoring this stuff (but it seems to me that's been said about SOAP as well, and look how successful that's been...)
Wednesday, 18 July 2007
Do mountains exist?
I came across this provocatively-titled paper while web-surfing looking for information on ontology. It's a fun read, if you're into that kind of stuff. I don't think the paper really tackles its proposed thesis in a head-on way, but it does raise some interesting points about the philosophy of geospatial data, such as:
- What is the real definition of a mountain? Sure, we all know one when we see one - or do we? Go ahead - try and define this concept in a rigourous way...
- There is a long-standing schism between between feature-based and field-based views of natural phenomena. Both are useful, in different contexts. (This seems to me to echo the particle-wave duality of quantum mechanics - is there possibly some sort of fundamental dichotomy going on here?)
- Every so often this kind of debate surfaces in the geospatial world (a recent example is this thread on the GeoWeb blog). But we are as babes in the wood compared to philosophers, who have been debating this topic for at least 2000 years. Fortunately, it looks like the kindergarten of computer science is beginning to engage in a useful dialogue with the fusty temples of philosophy.
Thursday, 12 July 2007
The ultimate Point-In-Polygon implementation
The classic stabbing line/ray-crossing point-in-polygon algorithm has been around for longer than computational geometry itself. (See William Franklin and SoftSurfer for background and description. ) The algorithm as usually published is short, effective and clever. But it does have some limitations:
Most recently, I've revisited P-I-P in the course of some work on improving the performance of spatial predicates. And I think I've finally arrived at the ultimate Point-In-Polygon implementation. It removes all of the above limitations with the following design features:
Coming soon to a JTS version near you...
- It is implemented as an iteration over a data structure representing a sequence of line segments. This ties the algorithm to a fixed data structure, which leads to code duplication
- It handles simple rings, but not fully general polygons (which may contain holes and/or multiple shells)
- It does not detect the case where the query point lies on one of the segments in the polygon
- It runs in O(n) time. This is reasonable for a single query point, but is not the most efficient way to perform many point queries against a single fixed polygon
- It uses conventional floating-point arithmetic. This makes it non-robust (i.e. potentially incorrect for some inputs)
Most recently, I've revisited P-I-P in the course of some work on improving the performance of spatial predicates. And I think I've finally arrived at the ultimate Point-In-Polygon implementation. It removes all of the above limitations with the following design features:
- It uses an incremental design, which frees the algorithm from being tied to any particular segment data structure
- It handles all polygonal geometry types defined in JTS. (Implementing this was made much cleaner by the pleasant realization that the PIP algorithm really doesn't care where in a polygonal geometry the segments come from. The only thing that matters is the parity of the segment crossings. This holds true for any number of holes and shells.)
- It detcts the point-on-segment case, and reports it via a trivalent return value (in the set {INTERIOR, BOUNDARY, EXTERIOR}).
- It is straightforward to use with a spatial index on the segments of the polygon (such as STRtree or BinTree), thus providing O(log n) performance
- Thanks to the RobustDeterminant class in JTS, the implementation is much more robust. (Due to some remaining floating-point arithmetic it may still not be 100% robust - but I hope to address that sometime as well.)
Coming soon to a JTS version near you...
Monday, 9 July 2007
Relations - the machine code for data?
In the rushing torrent of computer science, a few concepts stand like rocks which resist being swept away. One of the most familiar and useful is relational database technology. It took a relatively short time for this concept to be identified (in Codd's paper of 1970) and implemented commercially (around 1975, in IBM's System R, among others). Perhaps only 10 or 15 years elapsed between the earliest database systems and the emergence of commercially viable RDBMS . For over 30 years since then RDBMS's have stood the test of time and repelled all challengers to their central role in data management.
A recent and serious challenger was Object database technology. In the 1990's this area looked poised to ride the gathering wave of object-oriented programming and sweep aside the fusty old RDBMS technology. Since then, while the OO wave has swept far up the beach, the promise of ODBMS seems to have been left behind in the receding foam, never having been fully realized.
So why is this?
I think one reason is that the relational paradigm could be a fundamental data structure for information representation. In a sense, relations are the machine code of data modelling - they can be used to represent any required data model. Granted, relational models aren't alway elegant or efficient - but that simply confirms the metaphor. Moreover, their simplicity allows relational theory to be firmly grounded in mathematics and logic. (Of course, the relational hard-cores have been saying this for years - in some cases a bit too vociferously, IMHO. I'm just reluctantly coming round to think that they might be right.)
A further piece of evidence for this observation is that RDBMS vendors have a fine track record of being able to adapt the core paradigm to accomodate new technical ideas. Queuing, security models, data analytics, and of course even (to an extent) object-orientation are some of the areas which have been implemented quite reasonably in terms of an underlying relational model.
ODBMS's, in contrast, have never quite seemed to develop a truly compelling and general paradigm. The various OO query languages don't seem to have the expressive power of SQL, and Object data models seem to run up against thorny semantic issues sooner than relational ones do (such as schema evolution and inheritance modelling). Granted, implementing an object-based data model using relational technology doesn't actually solve any of these issues, but somehow the maturity of relational techniques and tools make them seem less painful.
Some people (myself included) have tended to see the rise of Object-Relational mapping technology as at best a temporary expedient, and at worst a string-and-baling-wire solution to cope with the OO-RDB impedance mismatch. Just give ODB's a few more years to mature, we hope, and we can do away with this inelegant hack! But if relational really is a fundamental concept, perhaps the quest for pure OO databases is misguided. Perhaps O-R mapping tools are the final goal, not just a stop-gap. They can be thought of as compilers for the data access layer (with all the opportunity for performance improvement and platform independence that the compilation paradigm provides).
This isn't to say that RDB technology has evolved as far as it needs to. I hope to see much more powerful querying capability, using concepts from the areas of logic and functional programming, machine reasoning and knowledge representation. All of these seem to be continuing to mature - I look forward to seeing them make the leap to practicality like OO did years ago.
Thursday, 21 June 2007
Packed 1-dimensional R-Tree for Geometric Algorithms

Some geometry algorithms depend on searching a fixed set of 1-dimensional intervals for the ones which contain a given value. An example is Point-In-Polygon testing using the stabbing line method. In cases where the algorithm needs to be run multiple times for different input values, the performance can be improved if a suitable data structure is used to increase the efficiency of search.
Here's an idea for an index which allows fast lookup of 1-dimensional intervals. It is basically a 1-dimensional R-tree, with a packing scheme which allows easy creation of the index for a fixed set of intervals. The index has the following charateristics:
- It indexes 1-dimensional intervals over some ordered set of values (for geometry, usually floating-point numbers)
- It indexes a static, pre-known set of items. Once built the index cannot be modified.
- Queries can be by either range or single value (stabbing queries), and return the set of all items which intersect the query value
- One optional parameter is the bucket size
To build the tree:
- sort all the intervals to be indexed by their midpoint. These form the leaf nodes of the tree.
- Create new interior nodes for every adjacent pair of nodes, assigning the new node to have an interval which spans the intervals of its children. If there is only one child available, do not create a new node for it.
- Recursively repeat the previous step, until a single node is created. This is the root node of the tree.
- traverse the tree in depth-first order, pruning branches which have intervals which do not intersect the query value.
The interior node definition can easily be generalized to allow n intervals per node (the bucket size). Of course, there's a trade-off between increasing fan-out and decreasing selectivity. It's not obvious to me where the sweet spot is.
Really this is a 1-dimensional version of Leutenegger & Edgington's STR tree. JTS even contains an implementation of this, using the generalized STRtree classes already in JTS. The novelty here is the exploration of just how simple the implementation of this structure can be. A simple implementation should be faster to build and query, as well - this is a subject for some performance testing.
There are several (lots?) of other data structures for efficiently querying sets of intervals. The segment tree and interval tree are probably the most well-known. Both of these structures are more complex to understand and implement, I believe. In addition, I don't think that they are amenable to an implementation based solely on two simple arrays.
Saturday, 16 June 2007
Presentations at FOSS4G 2007
I'm giving two talks at FOSS4G 2007, which is taking place here in Victoria in September. The abstracts are:
The JTS Topology Suite: Tools, Tips & Techniques
The JTS Topology Suite is one of the most widely used geometry libraries for Java. This talk will review the standard geometry methods in JTS, with an emphasis on their finer details. Some of the additional algorithms and components which the library provides will be discussed. Tips for improving performance and techniques for accomplishing various kinds of geometric processing tasks will be presented. The talk will conclude with an preview of some potential future developments for JTS.
If previous years are anything to go by, this conference should be very informative and energizing. See you there!
The JTS Topology Suite: Tools, Tips & Techniques
The JTS Topology Suite is one of the most widely used geometry libraries for Java. This talk will review the standard geometry methods in JTS, with an emphasis on their finer details. Some of the additional algorithms and components which the library provides will be discussed. Tips for improving performance and techniques for accomplishing various kinds of geometric processing tasks will be presented. The talk will conclude with an preview of some potential future developments for JTS.
Automatic watershed delineation using open source Java
The B.C. Corporate Watershed Base is a large-scale database of hydrographic information built using open source products. This talk discusses the development of an open source system for automated delineation of watershed boundaries based on CWB hydrography and a terrain model.If previous years are anything to go by, this conference should be very informative and energizing. See you there!
Sunday, 10 June 2007
History of JTS and GEOS
It seems a good thing to record the history and provenance of JTS and GEOS, for the following reasons:
Martin Davis, May 2007
- JTS and GEOS have attained a certain prominence in the open-source geospatial world. Sometimes comments are made which make assumptions about their goals and project structure which indicate a lack of knowledge about the true situation. Time to set the record straight!
- The legal attribution of code provenance bears little relationship to the true origin of the intellectual property incorporated in these projects. It seems only fair that the people who actually contributed to these projects have their participation recorded.
- As the designer/lead developer for these projects, I have the most knowledge about their origin and history.
JTS
JTS is the result of the fortuitous convergence of two situations. The first was that I had been working on spatial algorithms since the mid-90's. At that time I held a position in the BC Ministry of Forests, with a major focus being geomatics and spatial data management. While there I developed algorithms in C++ for polygonization and the beginnings of a polygon overlay algorithm. These were based on a simple spatial data model and included implementations of several fundamental computational geometric functions. A colleague, Brian Howden, was very encouraging in this work. Brian and I both felt that what the world really needed was a good spatial library, and this motivated me to start packaging my code as a reusable library. However, progress was slow and I did not feel like I had a clear idea of what such a library should look like. Moreover, library development in C++ was quite painful, since it requires such painstaking attention to details of memory management and code structure.
The second situation was my connection with Dr. Mark Sondheim, of the Geographic Data BC (GDBC) branch of the BC Ministry of Environment, Lands and Parks. I had known Mark since the early 90's, and had interacted with him on numerous occasions while I was working for the BC Government. Over the years we had many stimulating discussions about geospatial processing, and shared a similar interest in increasing the accessibility and formality of spatial data processing.
The JTS Topology Suite formally started life as a project conceived and initiated by Mark. The name and acronym were his idea, as was the concept of using the OGC Simple Features Specification as the basis for the API design. This latter idea was a key choice, since the SFS strikes a good balance between functionality and design complexity. Mark was confident that the SFS geometry model provided everything needed for most geospatial work, and time has proven him correct.
By 2000 I had moved to Vivid Solutions Inc. as a consultant, working primarily in Java and as much as possible on geospatial projects. While there I worked on a couple of spatial projects for GDBC which were Java based (most notably, a streaming parser for SAIF, a forerunner of GML developed by Mark Sondheim and others). I was also working on various projects which utilized my C++ spatial library (including some Java-based ones, necessitating the awkward and limiting use of JNI). Howver, there was never sufficient time or budget to contemplate re-implementing the C++ geometry library in Java (and, I have to admit, perhaps not the vision on my part that this would be as useful as it has turned out. In my defense, at that time Java was still proving itself as an efficient tool for development work).
Luckily, Mark did have the vision, and the access to funding. As a result, the JTS project was initiated in Fall 2000. The project goal was very clear: to develop a Java API which implemented the OGC Simple Features Specification. Given my experience and previous work, I suspect it was an easy choice to award the contract to Vivid Solutions. The project team consisted of myself as designer and lead developer, and Jonathan Aquino as a developer.
The project charter did not highlight the requirement for efficiency and robustness, since Mark wisely realized that these goals would have to be proven to be attainable during the course of the project. In hindsight the need for efficient performance should have been obvious; the need for robustness perhaps less so. (JTS is not exceptional in this area - a disappointly large percentage of published computational geometry algorithms fail to address this issue.) In any case, once the basic functionality was achieved, these two aspects emerged as much more important. Even today, they are still the most important issues in JTS development.
David Skea (at that time also with GDBC) contributed valuable direction and guidance. Most notably, it was his recommendation that an explicit precision model be provided, and he provided much insight about implementing robust spatial algorithms.
At the outset of the project it seemed that the main challenges were going to be designing the algorithms for spatial relationships and polygon overlay. Buffering was lurking in the background with an unknown level of difficulty. Mike Butler (the "father of SDE") had warned me that buffering would be a significant challenge, but since at that time he was still under NDA to ESRI, he did not provide me with any implementation advice. Later in the project when I tackled buffering I found out how right he was!
Development proceeded fairly quickly, with myself tackling API and algorithm design, and Jon working on I/O and implementations of structural methods. Jon also worked on the Unit Test facilities. David Skea contributed the core of the line segment intersection implementation, including the key development of deVillier's robust 2x2 determinant algorithm. Yao Cui of GDBC did good work on categorizing and defining test cases for the spatial predicates (which now appear as part of the JTS validation tests, a useful body of work in its own right).
In the middle of the project I realized that spatial visualization would be essential for designing and debugging spatial algorithms, and I also realized that Java2D and Swing would provide a great platform to build a visualization tool. This led to the development on the TestBuilder as an important component in the JTS toolkit. Jon and I shared development of the TestBuilder. This experience was very valuable in our subsequent development of JUMP.
JTS 1.0 was released in February 2002. The scheduling of this release was primarily motivated by contractual requirements. As soon as it was released I continued work on validation and buffer improvements. This resulted in the release of Version 1.1 in March 2002. At this point the contract with GDBC came to an end. I was encouraged by the success of the JTS development, and I made a personal commitment to continue to enhance JTS with better and more algorithms.
Subsequent releases of JTS have been motivated by my desire to see the library grow, by bug reports and suggestions from clients and users, and occasionally by directly-funded work (notably, work I carried out in 2006 on improving the robustness of polygon overlay). JTS has moved beyond the basic SFS by providing functionality such as polygonization, simplification, linear referencing, affine transformations, and a wide variety of structural functions. One day perhaps it will even provide a true topology API !
It's fair to say that JTS has been wildly successful in fulfilling the goal of providing a full-featured, robust, efficient library of spatial operations. It is being used in numerous spatial applications, notably:
- JUMP (and derived projects)
- GeoTools (and derived projects),
- the BC Goverment/Moxie Media Internet Mapping Framework
GEOS
In 2003 PostGIS was emerging as a serious and useful spatial database. However, there was one thing it sorely lacked - a complete set of spatial functions. Paul Ramsey and I strategized that the functions in JTS were an excellent basis for filling this gap. The big catch was that PostGIS required a pure C implementation. Never being one to shy away from thinking big, Paul proposed that we port JTS to C++. At that time Dave Blasby was still involved with PostGIS development, and it was he who came up with the name of Geometry Engine (Open Source) - GEOS.
Initially the GEOS project was funded jointly by Refractions Research Inc. and Vivid Solutions, with myself as Technical Advisor (and to a limited extent Architect), and a University of Victoria Master's student named Yury Bychov as developer and designer. Since I was busy on other projects, and in any case would not claim to be an expert in the byzantine area of C++ code design, the plan was that Yury would provide any extra design needed to accomodate differences between Java and C++, and I would advise as much as possible on the purely functional design of the API.
We knew that C++'s lacks of automated memory management would be a major challenge, and I also expected that its much more flexible (some would say baroque) features for code organization (e.g. templates, namespaces) would require some careful thought. I had no idea that the porting process would be quite so painful and prolonged, however. In the end it took longer to port JTS to C++ than it did to develop the entirety of JTS up to Version 1.1! [This is the main reason why my strategy for designing and implementing spatial algorithms remains focussed on Java as the development language, with the GEOS port happening only after the algorithms are relatively stable and well-understood. In my opinion C++ is less effective for algorithm design since it requires too much brainpower devoted to irrelevant issues.]
Since its initial release GEOS has been incorporated in PostGIS, of course, and also in MapGuide and apparently in at least a few other C-based projects. GEOS code has been incorporated by Safe Software in their FME product. MapServer has announced plans to incorporate GEOS in their codebase (the status of this is unknown to me). Frank Warmerdam's OGR project I believe uses GEOS.
GEOS also continues to undergo development, both in the orginal mode of direct ports of JTS code, and also to a certain extent with independent functionality (primarily involving making it better adapted to C++ programming styles).Martin Davis, May 2007
Monotone Chains: the unknown technique
When I was originally developing JTS, I spent quite of bit of time thinking about and researching techniques for efficiently computing arrangements (intersections) of sets of linestrings. There's a relatively large body of literature on this subject, as you might expect since it is such a key aspect of many geometric algorithms. As usual, however, much of this literature is fairly academic in nature, and usually doesn't address some of the more mundane issues which an implementor has to deal with.
One issue that crops up with intersecting sets of linestrings is that there is a tension between increasing performance and decreasing memory use. The fastest way should be to indexing individual line segments. However, this implies creating a new memory structure for each line segment, which can be both time and memory intensive. The most memory-effective structure is of course to leave the original linestrings undivided, but this does not provide good performance.
It seemed to me that there must be an intermediate between these two extremes. After some thought I came up with the idea that I called "monotone chains". A monotone chain is a string of line segments which are monotonic in both X and Y directions. This structure has some nice properties:
I was pretty pleased with my "discovery", and used it to good effect in JTS. For quite a while I was unaware of any prior use of this technique, but recently I came across a reference to a paper by Warren Burton in 1977 which apparently discusses this technique. I was led to this by the paper on Whirlpool by Nick Chrisman et al., which used this technique under the name "monotone sections".
It doesn't come as too much of a surprise that such a simple and useful technique has been used before, but what I do find a bit surprising is how little this technique is discussed in computational geometry literature. I presume the reason for this is that the technique is too simple to be of continuing interest to academics, while it is too special-purpose to be worth presenting to students. There's a dearth of computational geometry literature directed at the true practitioner - which probably indicates how few practitioners there are!
References
Burton, Warren 1977: Representation of many-sided polygons and polygonal lines for rapid processing, Communications ACM, vol. 20, no.3.
Chrisman, N.R., Dougenik, J.A. and White, D. 1992: Lessons for the design of polygon overlay processing from the Odyssey Whirlpool algorithm, Proc. 5th Int. Symp. on Spatial Data Handling, 2, 401-410.
One issue that crops up with intersecting sets of linestrings is that there is a tension between increasing performance and decreasing memory use. The fastest way should be to indexing individual line segments. However, this implies creating a new memory structure for each line segment, which can be both time and memory intensive. The most memory-effective structure is of course to leave the original linestrings undivided, but this does not provide good performance.
It seemed to me that there must be an intermediate between these two extremes. After some thought I came up with the idea that I called "monotone chains". A monotone chain is a string of line segments which are monotonic in both X and Y directions. This structure has some nice properties:
- Monotone chains cannot self-intersect
- Two monotone chains intersect in at most one connected set of line segments.
- The envelopes of any two subsequences of a monotone chain are interior-disjoint. This means that the envelopes of successive bisections of the chain form a "pyramid" of envelopes. In turn, this allows comparing two chains for intersection can be carried out using a binary search technique using the two envelope pyramids.
I was pretty pleased with my "discovery", and used it to good effect in JTS. For quite a while I was unaware of any prior use of this technique, but recently I came across a reference to a paper by Warren Burton in 1977 which apparently discusses this technique. I was led to this by the paper on Whirlpool by Nick Chrisman et al., which used this technique under the name "monotone sections".
It doesn't come as too much of a surprise that such a simple and useful technique has been used before, but what I do find a bit surprising is how little this technique is discussed in computational geometry literature. I presume the reason for this is that the technique is too simple to be of continuing interest to academics, while it is too special-purpose to be worth presenting to students. There's a dearth of computational geometry literature directed at the true practitioner - which probably indicates how few practitioners there are!
References
Burton, Warren 1977: Representation of many-sided polygons and polygonal lines for rapid processing, Communications ACM, vol. 20, no.3.
Chrisman, N.R., Dougenik, J.A. and White, D. 1992: Lessons for the design of polygon overlay processing from the Odyssey Whirlpool algorithm, Proc. 5th Int. Symp. on Spatial Data Handling, 2, 401-410.
Saturday, 9 June 2007
Quirks of the "Contains" Spatial Predicate
One of the most useful OGC standards is their specification of the Dimensionally-Extended 9 Intersection Model for spatial relationships. (To give credit where is it due, this was originally developed by Egenhofer, Clementini and others). In its most general form this model is quite complex, so to make it usable for mortal programmers, a set of commonly-useful "named predicates" have been specified. These include obvious relationships such as intersects, disjoint, touches, equals, and contains.
But are they really so obvious? In fact not - several of them have subtle aspects to their definition which are contrary to intuition.
In particular, "contains" (and its converse "within") has an aspect of its definition which may produce unexpected behaviour. This quirk can be expressed as "Polygons do not contain their boundary". More precisely, the definition of contains is:
Geometry A contains Geometry B iff no points of B lie in the exterior of A, and at least one point of the interior of B lies in the interior of A
That last clause causes the trap - because of it, a LineString which is completely contained in the boundary of a Polygon is not considered to be contained in that Polygon!
This behaviour could easily trip up someone who is simply trying to find all LineStrings which have no points outside a given Polygon. In fact, this is probably the most common usage of contains. For this reason it's useful to define another predicate called covers, which has the intuitively expected semantics:
Geometry A covers Geometry B iff no points of B lie in the exterior of A
Its converse coveredBy is also useful as well. It's a bit of a mystery why OGC did not define this predicate. In any case, Oracle Spatial does provide this predicate. I have added it to JTS as well.
There's a further bonus to defining the covers predicate. It is much easier to optimize the common use case:
covers(Rectangle, Geometry)
All that is necessary to determine this condition is to perform a simple bounding box comparison. This is not possible with contains, because even if the bounding box of Geometry is covered by the Rectangle, a further expensive operation is required to test if the Geometry lies wholly in the boundary of the Rectangle (in which case the predicate fails).
Covers "simplifies" the defintion of contains by making it more general (inclusive). There's another possibility as well, which is to simplify in the direction of being less inclusive. This would produce a predicate which might be called containsProperly, with the definition:
Geometry A containsProperly Geometry B iff all points of B lie in the interior of A
Interestingly, some recent work I'm doing indicates that this predicate might play a very useful role - but that's a story for another post.
References
DE-9IM: Clementini, Eliseo, Di Felice, and van Osstrom; "A Small Set of Formal Topological Relationships Suitable for End-User Interaction," D. Abel and B.C. Ooi (Ed.), Advances in Spatial Database—Third International Symposium. SSD '93. LNCS 692. Pp. 277-295.
9 Intersection model: M. J. Egenhofer and J. Herring; "Categorizing binary topological relationships between regions, lines, and points in geographic databases," Tech. Report, Department of Surveying Engineering, University of Maine, Orono, ME 1991.
Monday, 14 May 2007
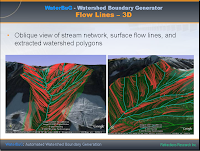
GeoTec 2007 presentation on Automated Watershed Boundary Generation
I'm giving a talk at GeoTec 2007 in Calgary entitled "WaterBuG: An Automated Generator for Watershed Boundaries". This covers a project I've been working on for the last year-and-a-half. It's a very cool application of complex large-scale geo-processing, using a whole assortment of nifty geometric structures and algorithms such as:
Here's a couple of screenshots from the talk - I'll post the full presentation sometime soon, somewhere...
- quad-edge subdivisions for modelling
- Triangular Irregular Networks (Delaunay triangulations)Delaunay triangulation refinement
- Medial axis refinement
- Surface modelling with a TIN
- Surface hydrological flow modelling over a TIN
- Flood filling
- Depth- and breadth-first Graph traversal
- Topology-preserving Linestring smoothing
- Discrepancy detection
Here's a couple of screenshots from the talk - I'll post the full presentation sometime soon, somewhere...


Subscribe to:
Posts (Atom)


